Agentic AI tooling and evaluation
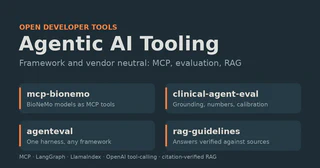
Open tools that make agentic AI easier to build, trust and evaluate. These are framework and vendor neutral, which is the point: the hard parts of agentic AI (discovery, evaluation, grounding) are the same whatever model you run.
Tools
mcp-bionemo. A Model Context Protocol server that exposes NVIDIA BioNeMo NIMs (RFdiffusion, ProteinMPNN, Boltz-2) as typed tools, so any MCP client can call them. BioNeMo ships as agent skills and raw endpoints but not as MCP, so this closes a real gap. Runs on a simulator by default, one flag switches to the live NIMs. github.com/AnhDuongVo/mcp-bionemo
clinical-agent-eval. A reusable harness that scores clinical agent outputs on grounding, number accuracy, hallucinated-citation rate and calibration, and renders a leaderboard. github.com/AnhDuongVo/clinical-agent-eval
agenteval (framework-agnostic). The same evaluation ideas generalized across agent frameworks (LangGraph, LlamaIndex, OpenAI tool-calling), so one harness scores traces from any of them.
rag-guidelines. Retrieval-augmented generation over public clinical guidelines and drug labels, with every answer verified against its cited source, on a neutral open stack.
Live demo
An interactive app (offline, no key needed) that runs the verification logic of the clinical agents: github.com/AnhDuongVo/clinical-agentic-ai-demo
